We embed chess positions into a continuous space where distance mirrors evaluation. By moving toward an “advantage vector” in that space, our engine plans moves without deep tree search, delivering super‑human strength with a tiny search budget.
TL;DR
- We replace deep tree search with planning in a learned latent space.
- Our engine reaches an estimated 2593 Elo using only a 6‑ply beam search.
- The approach is efficient, interpretable, and scales with model size.
Why it matters
Traditional chess engines such as Stockfish rely on exhaustive tree search that explores millions of positions and requires heavy hardware. Human grandmasters, by contrast, use intuition to prune the search space and then look ahead only a few moves. Replicating that human‑like intuition in an AI system could dramatically reduce the computational cost of strong play and make powerful chess agents accessible on modest devices. Moreover, a method that plans by moving through a learned representation is potentially transferable to any domain where a sensible state evaluation exists—games, robotics, or decision‑making problems.
How it works (plain words)
Our pipeline consists of three intuitive steps.
- Learning the space. We train a transformer encoder on five million positions taken from the ChessBench dataset. Each position carries a Stockfish win‑probability. Using supervised contrastive learning, the model pulls together positions with similar probabilities and pushes apart those with different probabilities. The result is a high‑dimensional embedding where “nearby” boards have similar evaluations.
- Defining an advantage direction. From the same training data we isolate extreme states: positions that Stockfish rates as forced checkmate for White (probability = 1.0) and for Black (probability = 0.0). We compute the mean embedding of each extreme set and subtract them. The resulting vector points from Black‑winning regions toward White‑winning regions and serves as our “advantage axis.”
- Embedding‑guided beam search. At run time we enumerate all legal moves, embed each resulting board, and measure its cosine similarity to the advantage axis. The top‑k (k = 3) most aligned positions are kept and expanded recursively up to six plies. Because the score is purely geometric, the engine prefers moves that point in the direction of higher evaluation, effectively “walking” toward better regions of the space.
The entire process requires no hand‑crafted evaluation function and no recursive minimax or Monte‑Carlo tree search. Planning becomes a matter of geometric reasoning inside the embedding.
What we found
Elo performance
We evaluated two architectures:
- Base model. 400 K training steps, 768‑dimensional embeddings, beam width = 3.
- Small model. Same training regime but with fewer layers and a 512‑dimensional embedding.
When we increase the search depth from 2 to 6 plies, the Base model’s estimated Elo improves steadily: 2115 (2‑ply), 2318 (3‑ply), 2433 (4‑ply), 2538 (5‑ply), and 2593 (6‑ply). The Small model follows the same trend but stays roughly 30–50 points behind at every depth. The 2593 Elo estimate at depth 6 is comparable to Stockfish 16 running at a calibrated 2600 Elo, yet our engine performs the search on a single GPU in a fraction of the time.
Scaling behaviour
Both model size and embedding dimensionality contribute positively. Larger transformers (the Base configuration) consistently outperform the Small configuration, confirming that richer representations give the planner better navigation cues. Early experiments with higher‑dimensional embeddings (e.g., 1024 D) show modest additional gains, suggesting a ceiling that will likely rise with even bigger models.
Qualitative insights
We visualized thousands of positions using UMAP. The plot reveals a clear gradient: clusters of White‑advantage positions sit on one side, Black‑advantage positions on the opposite side, and balanced positions cluster near the origin. When we trace the embeddings of actual games, winning games trace smooth curves that move from the centre toward the appropriate advantage side, while tightly contested games jitter around the centre. These trajectories give us a visual proof that the embedding captures strategic progress without any explicit evaluation function.
Interpretability
Because move choice is a cosine similarity score, we can inspect why a move was preferred. For any position we can project its embedding onto the advantage axis and see whether the engine is pushing toward White‑dominant or Black‑dominant regions. This geometric view is far more transparent than a black‑box evaluation network that outputs a scalar score.
Key equation
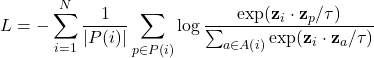
Here,  is the embedding of the i‑th board state,
 denotes the set of positives (positions whose Stockfish evaluations differ by less than the margin = 0.05),
 is the full batch, and
 is the temperature parameter. This supervised contrastive loss pulls together positions with similar evaluations and pushes apart those with dissimilar evaluations, shaping the latent space for geometric planning.
Limits and next steps
Current limitations
- Greedy beam search. With a beam width of three, the search cannot revise early commitments. Long‑term tactical ideas that require a temporary sacrifice can be missed.
- Training target dependence. Our contrastive objective uses Stockfish evaluations as ground truth. While this provides high‑quality numerical signals, it may not capture the nuanced strategic preferences of human players.
Future directions
- Replace the greedy beam with more exploratory strategies such as wider or non‑greedy beams, Monte Carlo rollouts, or hybrid search that combines latent scoring with occasional shallow alpha‑beta pruning.
- Fine‑tune the embedding with reinforcement learning, allowing the engine to discover its own evaluation signal from self‑play rather than relying solely on Stockfish.
- Scale the transformer to larger depth and width, and enrich the positive‑pair sampling (e.g., include mid‑game strategic motifs) to sharpen the advantage axis.
- Apply the same representation‑based planning to other perfect‑information games (Go, Shogi, Hex) where a numeric evaluation can be generated.
FAQ
- What is “latent‑space planning”?
- It is the idea that an agent can decide which action to take by moving its internal representation toward a region associated with higher value, instead of exploring a combinatorial tree of future states.
- Why use supervised contrastive learning instead of ordinary regression?
- Contrastive learning directly shapes the geometry of the space: positions with similar evaluations become neighbours, while dissimilar positions are pushed apart. This geometric structure is essential for the cosine‑similarity scoring used in our search.
- How does the “advantage vector” get computed?
- We take the mean embedding of forced‑checkmate positions for White (p = 1.0) and the mean embedding of forced‑checkmate positions for Black (p = 0.0) and subtract the latter from the former. The resulting vector points from Black‑winning regions toward White‑winning regions.
- Can this method replace Monte‑Carlo Tree Search (MCTS) in AlphaZero‑style agents?
- Our results show that, for chess, a well‑structured latent space can achieve comparable strength with far shallower search. Whether it can fully replace MCTS in other domains remains an open research question, but the principle of geometric planning is compatible with hybrid designs that still retain some tree‑based refinement.
- Is the engine limited to Stockfish‑derived data?
- In its current form, yes; we use Stockfish win‑probabilities as supervision. Future work plans to incorporate human annotations or self‑play reinforcement signals to reduce this dependency.
Read the paper
For a complete technical description, training details, and additional visualizations, see our full paper:
Learning to Plan via Supervised Contrastive Learning and Strategic Interpolation: A Chess Case Study
If you prefer a direct download, the PDF is available here: Download PDF
Reference
Hamara, A., Hamerly, G., Rivas, P., & Freeman, A. C. (2025). Learning to plan via supervised contrastive learning and strategic interpolation: A chess case study. In Proceedings of the Second Workshop on Game AI Algorithms and Multi‑Agent Learning (GAAMAL) at IJCAI 2025 (pp. 1–7). Montreal, Canada.